Independent test · 21 October 2026 · Clairic preview
Clairic, two days in
On 19 October Cloudflare released Clairic, a new kind of model that reads documents and fills in fields. We tested the preview on 503 real order emails and 711 receipt photos, next to five LLMs. It is the fastest and most consistent model we tested. It is not yet the most reliable one.
This is a two-day-old preview. Cloudflare says Clairic will improve with each checkpoint, and we expect it to. Everything below describes the hosted model on 20-21 October 2026. We will run the same tests on the next version.
The model
What Clairic does
An LLM writes its answer one word at a time. Clairic does not write. You give it a document and a list of named fields, and it returns one typed value per field in a single pass: a piece of text, a number, a date. For each value it also returns a confidence and a probability that the value is not in the document at all. Cloudflare calls this a "System One extraction model".
The launch post says it is faster, cheaper and more accurate than LLMs for this kind of work, and that it returns empty instead of guessing when a value is missing. We tested those claims on two jobs that matter for real automation: reading orders from customer emails, and reading totals from receipt photos.
Finding 01
Where Clairic is strong
Speed and consistency are real. Clairic was the fastest model in every test, and it gave the same answer to the same input almost every time.
Clairic answers fastest
Median time per email, 100 emails, one model at a time. Lower is better.
Sequential calls from one GCP VM · 2026-10-20
Clairic gives the same answer every time
Share of answers that changed when the same 100 emails were sent three times. Lower is better.
426 answers per model · each vendor's default sampling
It also reads values that are clearly printed. It read the printed total on 95% of receipts and the quantity on 97.6% of email lines. And when nothing on a receipt could tell the total, it said so on 99.6% of them, as did every LLM.
Finding 02 · Customer emails
It fills in values that are not there
We took 503 real request-for-quote emails from one of our customers, an industrial instruments distributor. For every ordered product, each model had to return the part number and the quantity, or nothing if the email did not state them. Two models labelled the answers independently, and we checked every disagreement by hand.
The test that matters for automation is the empty case. A wrong part number that looks right is worse than no answer, because it goes straight into a quote.
Asked for a part number the customer never wrote
Share of answers that returned a part number anyway. Lower is better.
515 product lines with no part number in 503 real order emails (GLM-5.3: 384)
We deleted the quantity. Who still gave one?
Share of answers with a quantity after it was removed from the email. Lower is better.
435 deletions (GLM-5.3: 328) · when other lines still showed quantities, Clairic: 54%
What Clairic returns instead is usually real text from nearby: the product description, a size such as "20-50mm", another line's code, or "2 Nos". Its probability that the value is missing stayed low on these answers (median 0.07 for part numbers), so the empty signal alone does not catch them.
Reading a part number that is there
Share of part numbers read exactly as the customer wrote them. Higher is better.
589 part numbers (GLM-5.3: 463) · quantities: Clairic 97.6%, all LLMs 98.9-99.9%
How much can you fill in without a human?
Largest share of answers you can accept, sorted by the model's own confidence, and still be right 99% of the time.
Part numbers and quantities on the unedited emails · higher is better
Finding 03 · Receipt photos
It reads a total, but does not work one out
We took 711 public receipt photos where the items, tax and total add up exactly. Then we put a yellow sticker over more and more of the amounts and asked every model for the total.
One receipt, four stickers
Every model got the same photo and the same question: what is the total? The real total is 283,338 rupiah.
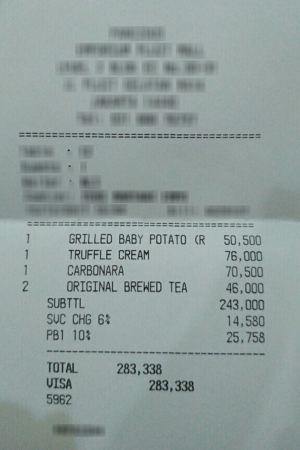
A · Nothing covered
Read the total
- Clairic283,338
- Haiku 5.5283,338
- Gemini 3.8 Flash283,338
- Sonnet 5.5283,338
- Opus 5.5283,338
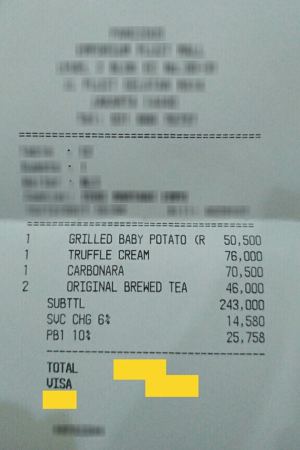
B · Total covered
Subtotal + tax still visible
- Clairic25,758
- Haiku 5.5283,338
- Gemini 3.8 Flash283,338
- Sonnet 5.5283,338
- Opus 5.5283,338
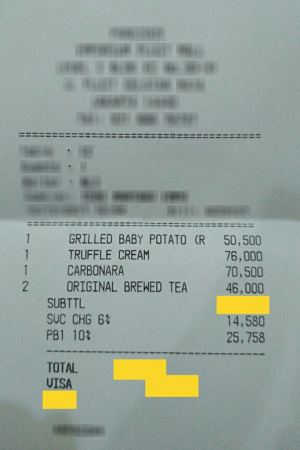
C · Total + subtotal covered
Add up the items + tax
- Clairic257,558
- Haiku 5.5283,338
- Gemini 3.8 Flash283,338
- Sonnet 5.5283,338
- Opus 5.5283,338
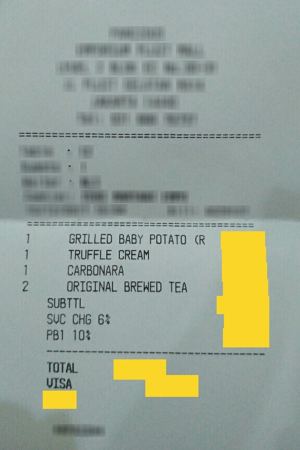
D · All amounts covered
Right answer: can't tell
- Clairiccan't tell
- Haiku 5.5can't tell
- Gemini 3.8 Flashcan't tell
- Sonnet 5.5can't tell
- Opus 5.5can't tell
CORD-v2 receipt validation_34 (public, CC-BY 4.0) · green = right, red = wrong
Right answers on 711 receipts
Each panel is one sticker version. Higher is better.
A · Read the printed total
B · Total covered
C · Total and subtotal covered
D · Everything covered: says can't tell
711 receipts × 4 versions × 5 models · a sticker on an empty area changed no model by more than 1.2 points
With the total covered, the LLMs worked it out 90%-98% of the time. Clairic did 34%. Often it had the right number: its hidden best guess, which it returns beside the answer, was right on 62% of these receipts. But its own threshold turned that guess into "can't tell". Other times it reported the tax line or the item sum as the total.
Working out the total, by number of items
Version C: total and subtotal covered. Share right.
| Model | 1 item (338) | 2 items (172) | 3-5 items (156) | 6+ items (45) |
|---|---|---|---|---|
| Clairic | 37% | 37% | 33% | 4% |
| Claude Haiku 5.5 | 84% | 95% | 98% | 93% |
| Gemini 3.8 Flash | 95% | 98% | 97% | 98% |
| Claude Sonnet 5.5 | 96% | 96% | 88% | 67% |
| Claude Opus 5.5 | 98% | 99% | 97% | 89% |
Receipt counts in brackets
Finding 04
The launch claims
Cloudflare's launch claims, checked
Our measurement on this data, not a general verdict.
| Claim | What we measured | Result |
|---|---|---|
| Faster than LLMs | Median 0.36 s per email against 1.03-3.84 s | Holds |
| Same answer every run | 0.2% of answers changed over three runs | Holds |
| Cheaper | $0.31 per 1,000 emails against $0.25 for Claude Haiku 5.5; receipts $0.23 against $0.28 | Close to Haiku |
| Thirty fields cost about the same as three | 30 fields cost 12.5 times as much as 2: about one pass per field, each re-reading the email | Not on our data |
| Returns null when a value is not in the input | Returned a part number for 68% of lines that had none | Not on our data |
| One- and two-step sums are reliable | Total from subtotal + tax: 54% right, LLMs 92%-99% | Not on our data |
| Use confidence to decide what to automate | Confidence ranks answers well (0.89), but only 24% can be accepted at 99% precision; Haiku 90% | Partly |
Claims from the launch post, 2026-10-19 · preview checkpoint
Practical advice
How we would use it today
- Good fit: high-volume reading of values that are clearly printed, where speed matters and a person or a rule checks the result.
- Check missing values: do not rely on an empty answer to mean "not there". Treat low-confidence answers as unknown.
- Do the maths in code: ask Clairic for the parts (items, tax) and add them up yourself. Cloudflare's post gives the same advice.
- Ask for fewer fields per call: cost and time grow with the number of fields.
- Where a missing value is costly, a small LLM such as Claude Haiku 5.5 was more accurate at about the same price in both tests.
Method
How we tested
- Emails: 503 real emails, 1,187 product lines. Answers labelled by Claude Opus 5.5 and Gemini 3.8 Flash independently, 70 hand decisions, two audits of 150 lines with no clear errors. Each model got the email and a short description of each product. Three kinds of empty case: never written, deleted by us, and a control where we deleted an ordinary word (no model changed by more than 1.2 points). Rules and predictions were written down before the full run.
- Receipts: CORD-v2 (public, CC-BY 4.0), 711 receipts that add up exactly. Five versions each, including a sticker on an empty area as a control. No model returned a memorised total on fully covered receipts.
- Fairness: all models got the same text or image and the same instruction. Clairic's field instructions included "leave it empty if not stated", the same rule the LLMs had; without it Clairic filled in more values.
- Our mistakes, fixed and disclosed: 39 receipts with cents were parsed 100 times too large by our script and were dropped. Our receipt question said "amount paid", which led Claude Haiku 5.5 to report the cash handed over 119 times; that lowers Haiku's reading score, not Clairic's. GLM-5.3 finished 1,249 of 1,626 email copies because of rate limits.
- Limits: one customer's emails (mostly English), one receipt dataset (Indonesian), text-only emails. Clairic has no version pinning; these results describe the hosted preview on 20-21 October 2026.
Nikhil Mudholkar · Bryo · independent test, not sponsored by any vendor.